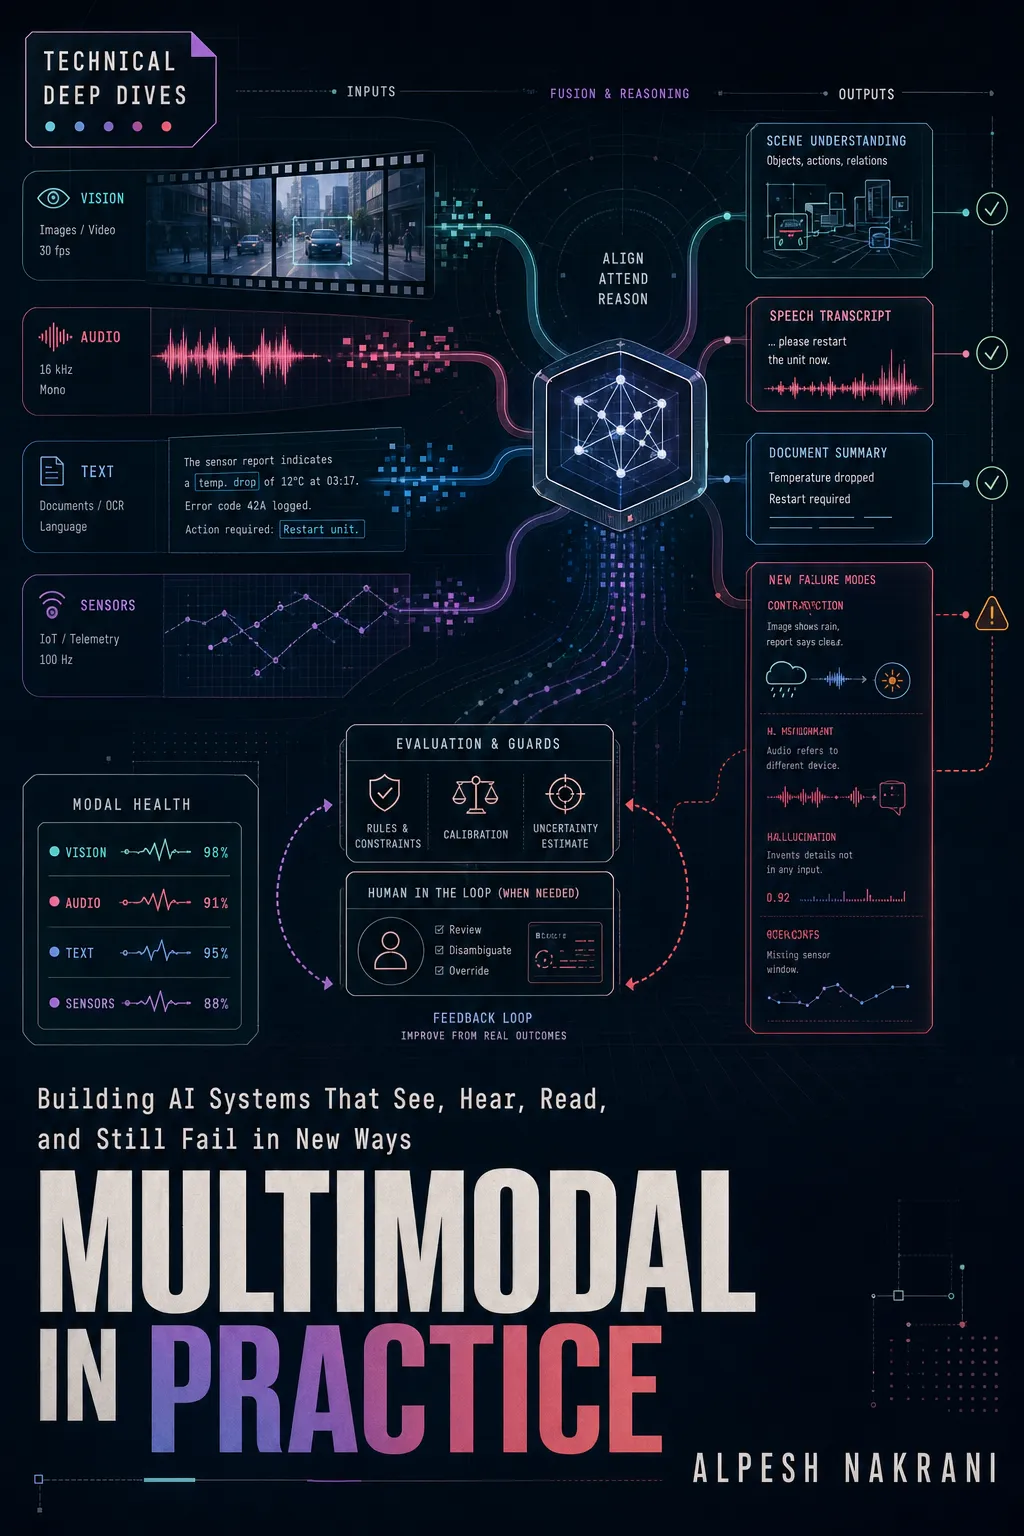
Multimodal in Practice
Building AI Systems That See, Hear, Read, and Still Fail in New Ways
A book by Alpesh Nakrani
Subscribe to get the complete book. Your PDF downloads immediately.
- Pages
- 150
- Chapters
- 16
- Format
- PDF · 27.6 MB
What's in the book
Adding images and audio to a system is not a parameter change. It is a new set of failure modes. This deep dive covers what multimodal models actually perceive, where they hallucinate differently, and the evaluation that catches it.
Vision and audio change the failure modes, not just the inputs. What breaks when the model has to see and hear.
Table of contents
PDF page- FMFront Matter: Multimodal in Practice—
- INTIntroduction: The Photo of the Bumper17
- 01The Demo Is Not the System23
- 02Every Modality Brings Its Own Blind Spots31
- 03A Vision Answer Is Not Evidence39
- 04Encoders, Contrastive Learning, and Cross-Modal Alignment47
- 05Joint Embedding Spaces and Their Limits54
- 06Documents Are Multimodal Objects61
- 07OCR Is Not Document Understanding68
- 08Grounding, Bounding Boxes, and Visual Citations75
- 09Audio Is Not Text After Transcription82
- 10Video Is Not Just Frames89
- 11Multimodal RAG and Cross-Modal Search96
- 12Evaluation: Seeing Is Not Verifying103
- 13Production Architecture for Multimodal Systems110
- 14Cost, Latency, and the Price of Vision Tokens117
- 15Privacy, Safety, and High-Stakes Images124
- 16The Use Case Field Guide131
- AAppendix A: Back Matter138
The full chapters, illustrations, and reference material are included in the downloadable PDF.
Multimodal in Practice
The complete edition,
ready to read offline.
Get your free copy.
Subscribe to Alpesh’s book and writing updates. Unsubscribe anytime.
Your download is ready.
You’re subscribed. Your PDF download should start automatically.
Download PDF againIf it doesn’t start, use the button above.